§ Essay
FastAPI 从入门到实战
FastAPI 从简单到入门的教程,涵盖最简单的接口创建、请求参数处理、响应类型,深入讲解中间件原理与应用、依赖注入机制、ORM,以及数据库操作
FastAPI 是基于 Python 类型提示的现代高性能 Web 框架,上手简单且性能优异。本文从最基础接口写起,逐步讲解参数处理、响应模型、中间件、依赖注入与 ORM 数据库操作,带你完成 FastAPI 从入门到实战。
一、FastAPI 介绍
前言
fastAPI 是大模型部署的核心能力,利用 fastAPI构建自己的大模型,,并且提供出一个可以访问的地址,供其他应用接入我们的大模型
大模型工程师核心能力:
- python 基础
- 服务化能力:通过 Python Web 框架将模型从本地代码部署为可在线访问、可扩展且稳定运行的服务
- AI 大模型开发能力:模型训练 、构建、微调、优化等
Python 框架千千万,fastAPI 框架是首选
| 对比维度 | FastAPI | Flask | Django |
|---|---|---|---|
| 性能 | 高(异步支持) | 中 | 较低(同步) |
| 异步支持 | 内置 async / await | 需扩展 | 不原生 |
| 数据验证 | Pydantic 自动校验 | 手动处理 | ORM 级验证 |
| 自动文档 | 自动生成 | 需插件 | 需扩展 |
| 使用场景 | API、微服务、AI推理 | 小型 Web 项目 | 大型网站 |
fastAPI 优势
fastAPI 是一个基于 Python 的高性能 Web 框架,专门用于快速构建 API 接口服务,原生异步支持,释放真正性
1、异步支持
让我们模拟一下同步与异步代码:
同步
@app.get("/sync")
def func_sync():
    start = time.time()
    for i in range(10):
        time.sleep(1)
    end = time.time()
    return {"time": f'{end-start:.2f}s'}
{
"time": "10.04s"
}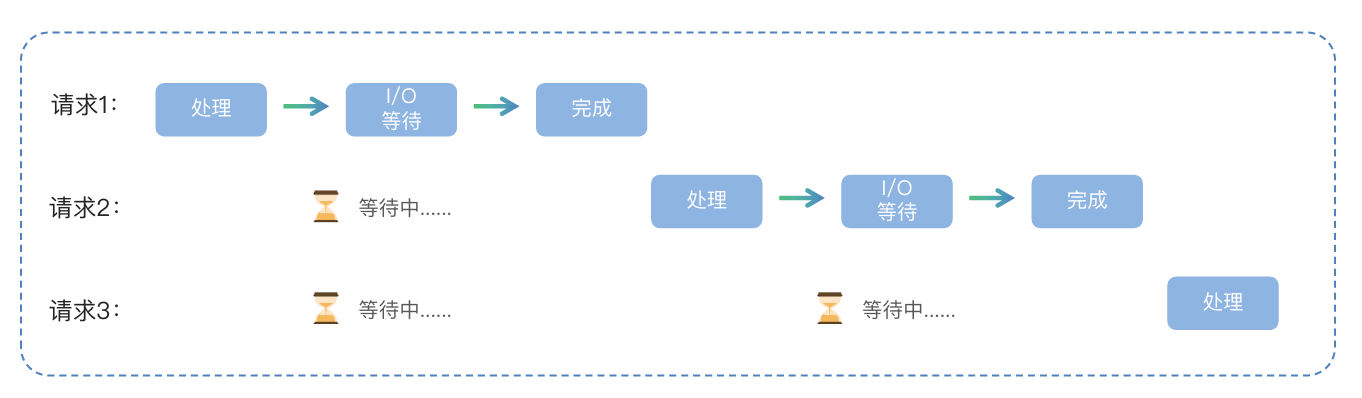
HTTP 请求、数据库、文件写入都是需要等待的 I/O 操作,易造成阻塞
异步
@app.get("/async")
async def func_async():
    start = time.time()
    tasks = [asyncio.sleep(1) for i in range(10)]
    await asyncio.gather(*tasks)
    end = time.time()
    return {"time": f'{end-start:.2f}s'}
{
"time": "1.00s"
}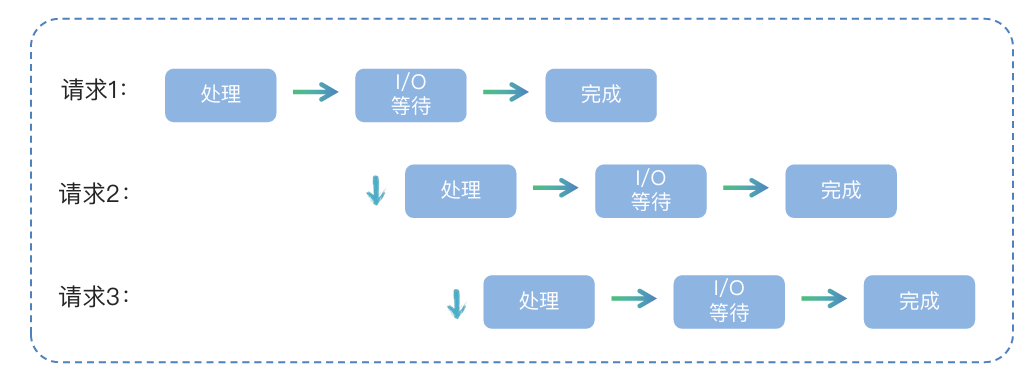
而异步遇到 I/O 操作时会切换任务
2、类型提示与数据验证
Pydantic 类型提示与验证,减少手动校验代码
from pydantic import BaseModel

class User(BaseModel):
    username: str
    password: str

@app.post("/register")
async def register(user: User):
    return user
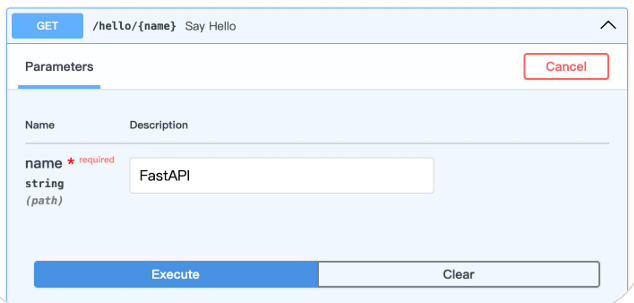
3、可交互式文档
自动生成可交互式文档,浏览器中直接调用和测试 API
二、FastAPI 基础入门
1、第一个 FastAPI 程序
创建 FastAPI 项目
new project —> FastAPI —> 创建
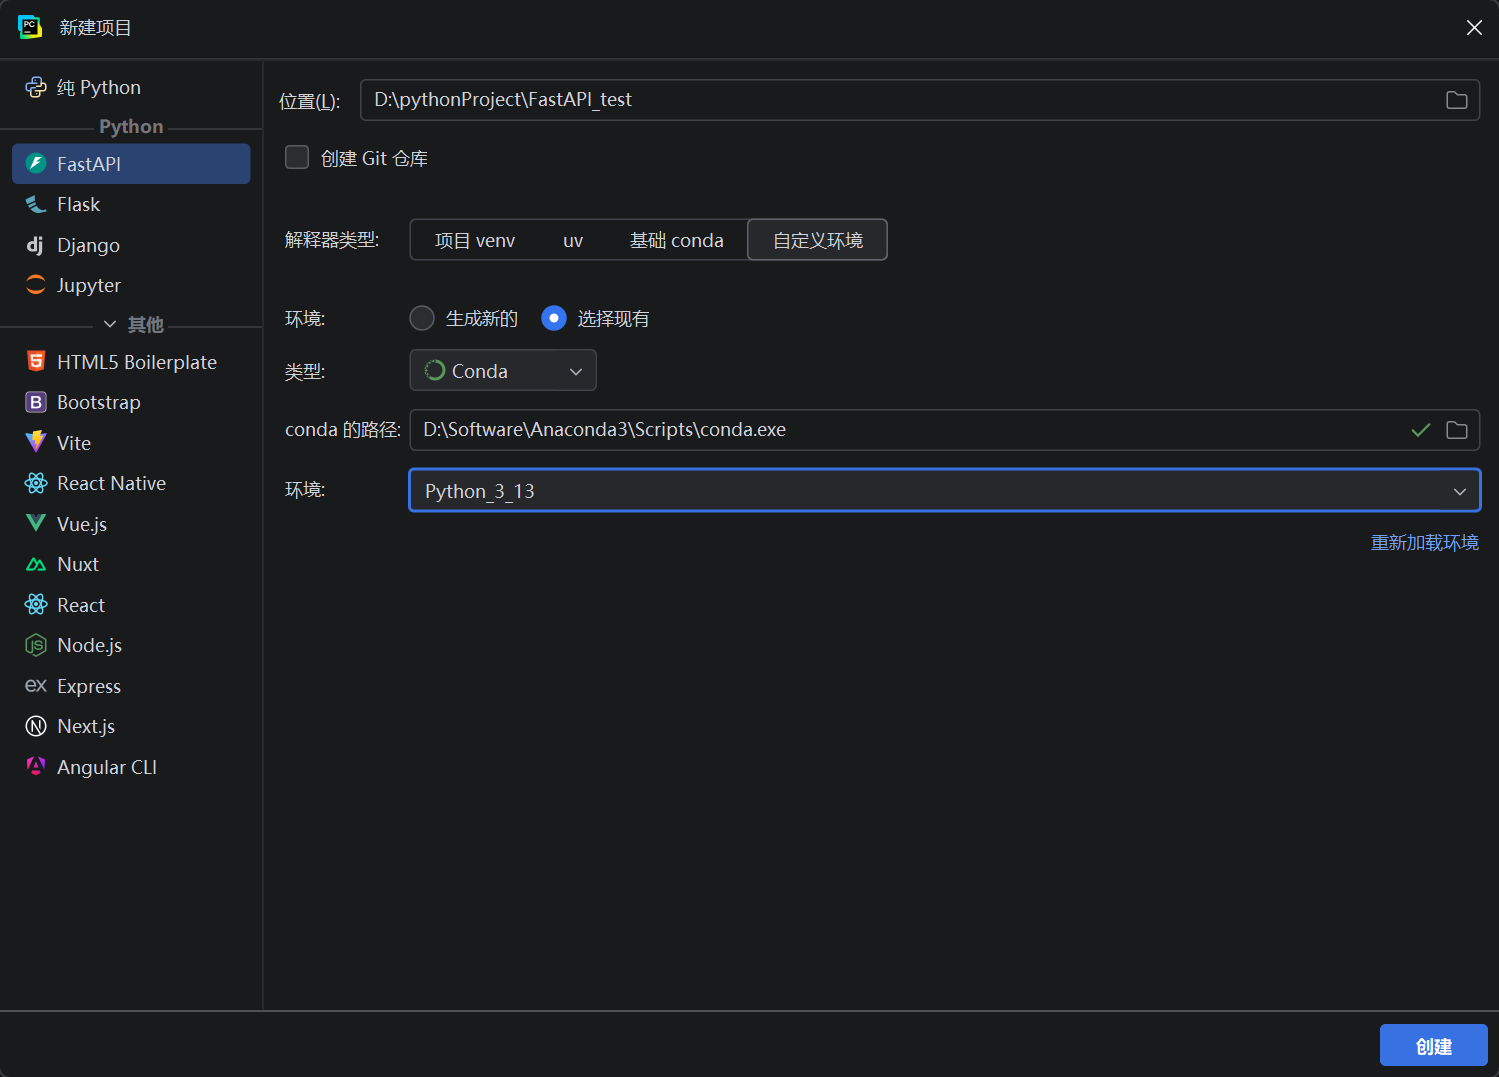
创建完成后自动生成两个文件,其中 main.py:
from fastapi import FastAPI

# 创建 FastAPI 实例
app = FastAPI()

# async 修饰的函数会变成异步函数
@app.get("/")
async def root():
    return {"message": "Hello World"}

@app.get("/hello/{name}")
async def say_hello(name: str):
    return {"message": f"Hello {name}"}
运行 FastAPI 项目
-
右上角 Run
-
命令行:
uvicorn main:app或:
# reload 修改代码自动重启服务器。右上角 Run 也是同样的效果
uvicorn main:app --reload
查看可交互式文档
浏览器输入:127.0.0.1:8000/docs
点击 try it out 可在线调试
2、路由
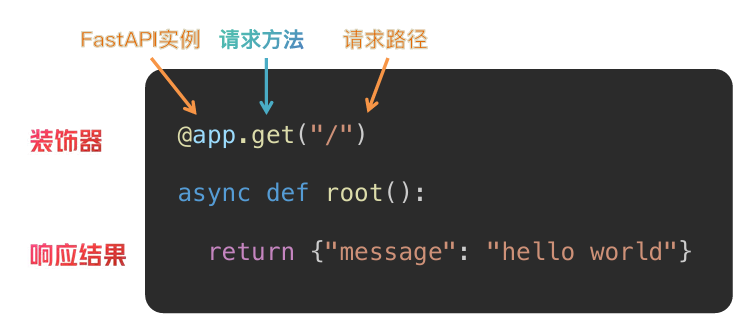
路由就是 URL 地址和处理函数之间的映射关系,它决定了当前用户访问某个特定网址时,服务器应该执行哪段代码来返回结果
fastAPI 的路由定义基于 Python 的装饰器模式
3、参数和路径参数
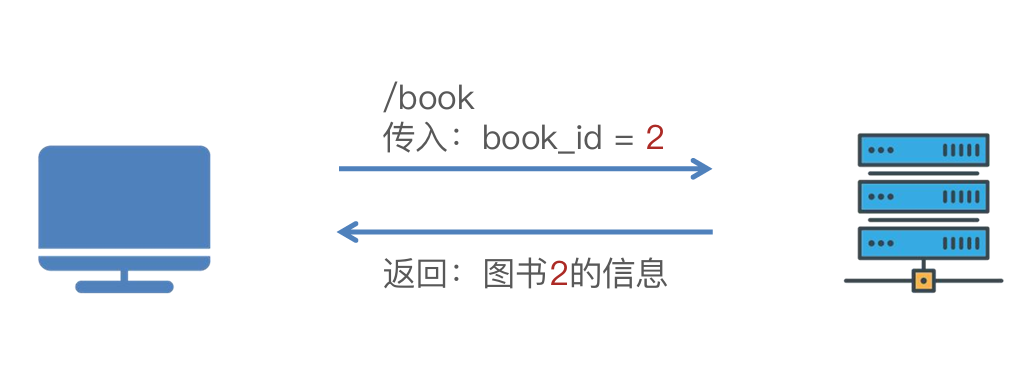
参数就是客户端发送请求时附带的额外信息和指令
参数的作用是让同一个接口能根据不同的输入,返回不同的输出,实现动态交互
同一段接口逻辑,根据参数不同返回不同的数据
参数分类:
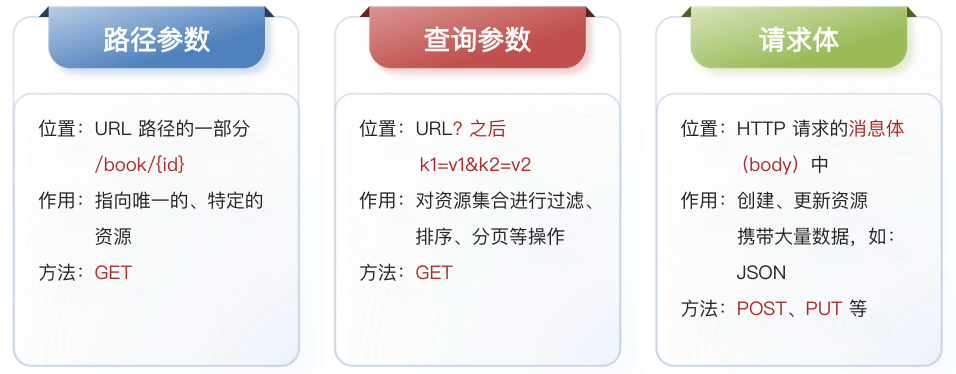
(1)路径参数
例子:
# 路径参数
@app.get("/book/{id}")
async def get_book(id: int):
    return {"id": id, "title": f"这是第{id}本书"}
Path 类型注解
FastAPI 允许为参数声明额外的信息和校验
需要导入 FastAPI 的 Path 函数
常用参数:
| Path 参数 | 说明 |
|---|---|
| ··· | 必填 |
| gt/ge le/le | 大于/大于等于 小于/小于等于 |
| description | 参数描述 |
| min_length max_length | 长度限制 |
| title | 参数标题 |
例子:
from fastapi import FastAPI, Path

app = FastAPI()

@app.get("/book/{id}")
async def get_book(id: int = Path(..., gt=0, lt=101, description="书籍id,取值范围1-100")):
    return {"id": id, "title": f"这是第{id}本书"}
(2)查询参数
声明的参数不是路径参数时,路径操作函数会把该参数自动解释为查询参数
查询参数通过 URL 的 query string 传递(?key=value)
例子:
@app.get("/news/news_list")
async def get_news_list(skip: int, limit: int=10):   # limit 默认值为 10
	return {"skip": skip, "limit": limit}
Query 类型注解
例子:
@app.get("/news/news_list")
async def get_news_list(
    skip: int = Query(0, description="跳过的记录数", lt=100),
    limit: int = Query(10, description="返回的记录数")
):
    return {"skip": skip, "limit": limit}
示例请求:
GET /items/?skip=0&limit=10(3)请求体参数
请求体参数通过 HTTP 请求体传递,通常使用 JSON 格式,需要定义 Pydantic 模型
在HTTP协议中,一个完整的请求由三部分组成:
- 请求行:包含方法、URL、协议版本
- 请求头:元数据信息(Content-Type、Authorization等)
- 请求体:实际要发送的数据内容
请求体参数写法:
-
定义类型
from pydantic import BaseModel class User(BaseModel): username: str password: str -
类型注解
@app.post("/register")
async def register(user: User):
	return user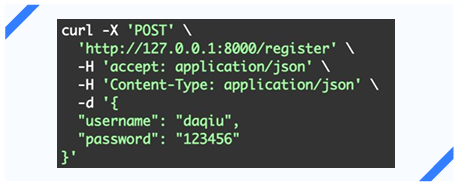
Field 类型注解
注意:与路径参数和查询参数不同的是,Field 是 pydantic 中的函数,而不是 fastAPI 原生的
例子:
from fastapi import FastAPI, Query
from pydantic import BaseModel, Field

app = FastAPI()

class User(BaseModel):
    username: str = Field(default="张三", min_length=2, max_length=10, description="用户名,长度要求2-10个字")
    password: str = Field(min_length=3, max_length=20)

@app.post("/register")
async def register(user: User):
    return user
示例请求:
POST /items/
{
    "username": "张三",
    "password": "123456",
}
4、请求与响应
HTTP 请求流程
客户端请求 → FastAPI 路由匹配 → 参数解析 → 业务处理 → 返回响应 → 客户端接收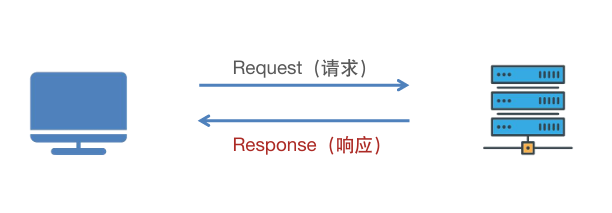
默认情况下,FastAPI 会自动将路径操作函数返回的 Python 对象(字典、列表、Pydantic 模型等),经由 jsonable_encoder 转换为 JSON 兼容格式,并包装为 JSONResponse 返回。这省去了手动序列化的步骤,让开发者能更专注于业务逻辑。 如果需要返回非 JSON 数据(如 HTML、文件流),FastAPI 提供了丰富的响应类型来返回不同数据:
| 响应类型 | 说明 | 示例 |
|---|---|---|
JSONResponse | JSON 格式响应(默认) | return {“key”: “value”} |
HTMLResponse | HTML 格式响应 | return HTMLResponse(html_content) |
PlainTextResponse | 纯文本响应 | return PlainTextResponse(“text”) |
RedirectResponse | 重定向响应 | return FileResponse(path) |
StreamingResponse | 流式响应(文件下载) | 生成器函数返回数据 |
FileResponse | 文件响应 | return RedirectResponse(url) |
ORJSONResponse | 高性能 JSON 响应 | return ORJSONResponse(content={“msg”:“message”}) |
其中JSONResponse、HTMLResponse、FileResponse 较为常用
响应类型设置方式
-
装饰器中指定响应类
场景:固定返回类型(HTML、纯文本等)
@app.get("/html", response_class=HTMLResponse) async def get_html(): return "<h1>这是标题</h1>" -
返回响应对象
场景:文件下载、图片、流式响应
@app.get("/file")
async def get_file():
	file_path = "./files/1.jpeg"
	return FileResponse(file_path)
示例 1:响应 HTML 格式
from fastapi import FastAPI
from fastapi.responses import HTMLResponse

app = FastAPI()

# 装饰器中指定响应类
@app.get("/", response_class=HTMLResponse)
async def read_root():
    html_content = """
    <html>
        <head>
            <title>FastAPI</title>
        </head>
        <body>
            <h1>Hello, FastAPI!</h1>
        </body>
    </html>
    """
    return html_content
示例 2:响应文件格式
FileResponse 是 FastAPI 提供的专门用于高效返回文件内容(如图片、PDF、Excel、音视频等)的响应类。它能够智能处理文件路径 、媒体类型推断、范围请求和缓存头部,是服务静态文件的推荐方式
from fastapi import FastAPI
from fastapi.responses import FileResponse

app = FastAPI()

"""
@app.get("/download")
async def download_file():
    return FileResponse(
        path="file.pdf",
        filename="download.pdf",
        media_type="application/pdf"
    )
"""
@app.get("/file")
async def get_file():
    path = "./files/1.jpeg"
    return FileResponse(path)
自定义响应(自己写个类)
response_model 是路径操作装饰器(如 @app.get或 @app.post)的关键参数,它通过一个 Pydantic 模型来严格定义和约束 API 端 点的输出格式。这一机制在提供自动数据验证和序列化的同时,更是保障数据安全性的第一道防线
from fastapi import FastAPI
from pydantic import BaseModel

app = FastAPI()

# 需求:新闻接口 → 响应数据格式 id、title、content
class News(BaseModel):
    id: int
    title: str
    content: str

@app.get("/news/{id}", response_model=News)
async def get_news(id: int):
    return {
        "id": id,
        "title": f"这是第{id}本书",
        "content": "这是一本好书"
    }

"""
class CustomResponse(JSONResponse):
    def render(self, content):
        # 自定义响应头
        self.headers["X-Custom-Header"] = "CustomValue"
        return super().render(content)

@app.get("/custom", response_class=CustomResponse)
def get_custom():
    return {"message": "Custom Response"}
"""
5、异常处理
对于客户端引发的错误(4xx,如资源未找到、认证失败),应使用 fastapi.HTTPException 来中断正常处理流程, 并返回标准错误响应
from fastapi import FastAPI, HTTPException
@app.get('/news/{id}')
async def get_news(id: int):
    id_list = [1, 2, 3, 4, 5, 6]
    if id not in id_list:
    	raise HTTPException(status_code=404, detail="当前id不存在")
    return {"id": id}

"""
items = {"foo": "The Foo Wrestlers"}

@app.get("/items/{item_id}")
def read_item(item_id: str):
    if item_id not in items:
        raise HTTPException(
            status_code=404,
            detail="Item not found",
            headers={"X-Error": "There goes my error"}
        )
    return {"item": items[item_id]}
"""
自定义异常处理器:
from fastapi import FastAPI, Request
from fastapi.responses import JSONResponse

app = FastAPI()

class UnicornException(Exception):
    def __init__(self, name: str):
        self.name = name

@app.exception_handler(UnicornException)
async def unicorn_exception_handler(request: Request, exc: UnicornException):
    return JSONResponse(
        status_code=418,
        content={"message": f"Oops! {exc.name} did something. There goes a rainbow..."}
    )

@app.get("/unicorns/{name}")
def read_unicorn(name: str):
    if name == "yolo":
        raise UnicornException(name=name)
    return {"unicorn_name": name}
三、FastAPI 进阶
1、中间件(Middleware)
使用中间件为每个请求前后添加统一的处理逻辑
啥时候会用到?
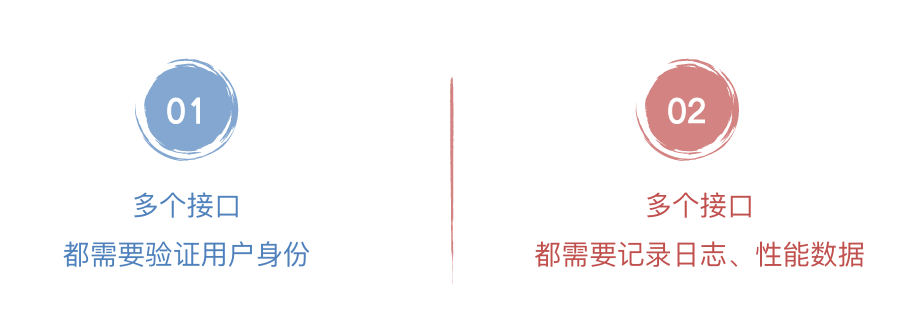
实际开发中以下事务都可以用中间件处理:
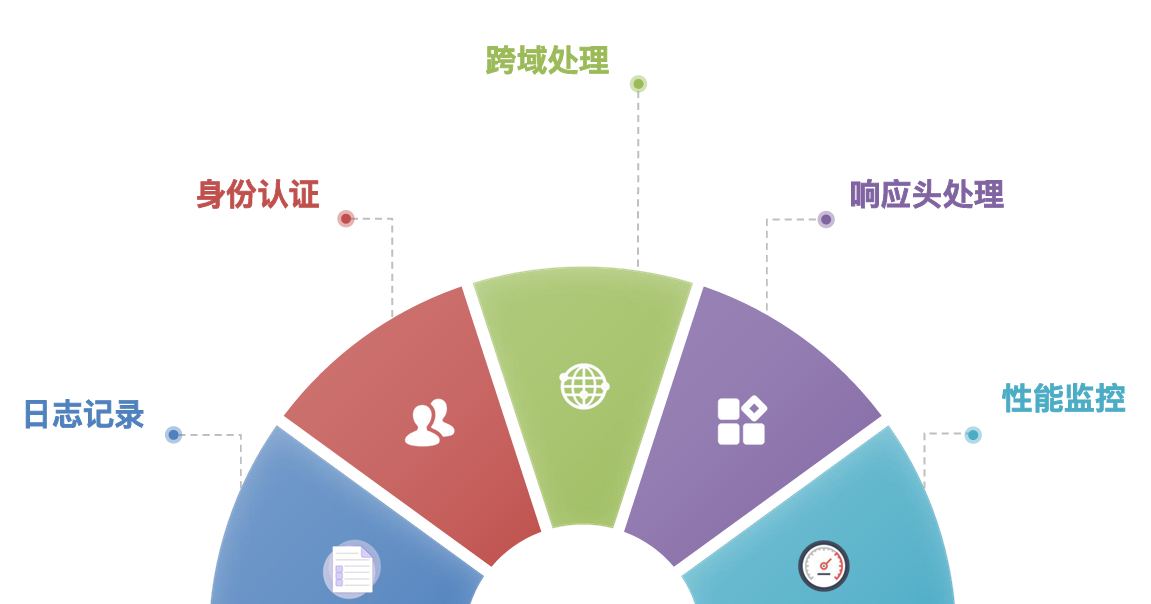
| 用途 | 说明 |
|---|---|
| 请求日志 | 记录所有请求信息 |
| CORS 处理 | 跨域资源共享配置 |
| 身份验证 | 验证 Token 或 Session |
| 响应头添加 | 添加统一的响应头 |
| 性能监控 | 记录请求处理时间 |
什么是中间件
中间件(Middleware)是一个在每次请求进入 FastAPI 应用时都会被执行的函数
它在请求到达实际的路径操作(路由处理函数)之前运行,并且在响应返回给客户端之前再运行一次
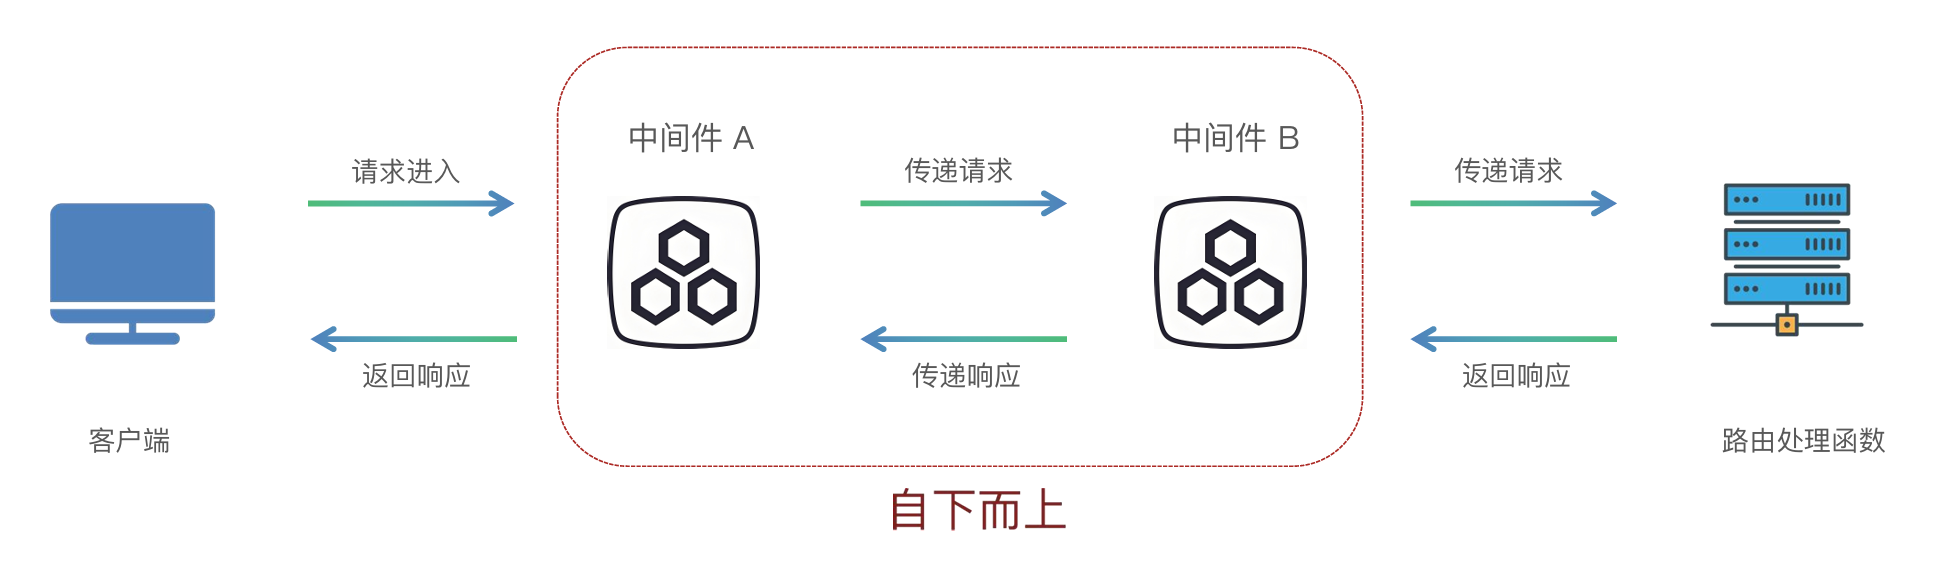
中间件执行顺序按代码顺序自下而上
请求 → 中间件1 → 中间件2 → ... → 路由处理 → ... → 中间件2 → 中间件1 → 响应中间件写法
函数的顶部使用装饰器 @app.middleware("http")
# request: 请求
# call_next: 传递请求给路径处理函数
@app.middleware("http")
async def middleware2(request, call_next):
    print("中间件2 start")
    response = await call_next(request)      # 向下传递请求,await 异步执行
    print("中间件2 end")
    return response

@app.middleware("http")
async def middleware1(request, call_next):
    print("中间件1 start")
    response = await call_next(request)
    print("中间件1 end")
    return response
中间件2 start
中间件1 start
中间件1 end
中间件2 end2、依赖注入(Dependency Injection)
使用依赖注入系统来共享通用逻辑,减少代码重复
为什么不用中间件做通用逻辑呢?
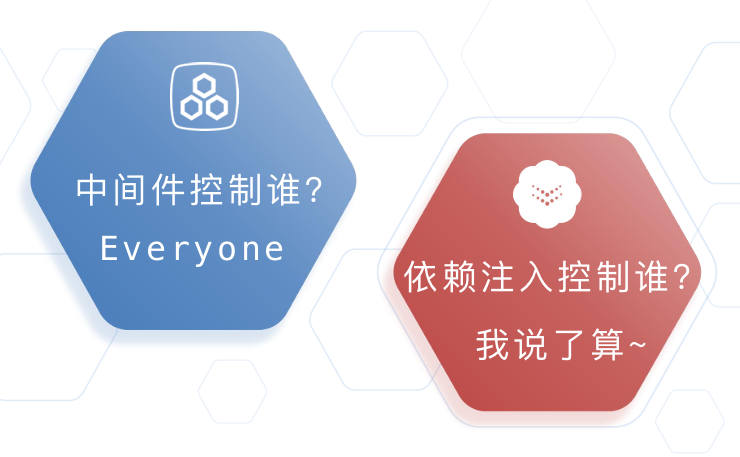
- 依赖项:可重用的组件(函数/类),负责提供某种功能或数据
- 注入:FastAPI 自动帮你调用依赖项,并将结果”注入”到路径操作函数中
优点
- 代码复用:一次编写,多处使用
- 解耦:业务逻辑与基础设施代码分离
- 易于测试:轻松地用模拟依赖替换真实依赖进行测试
应用场景
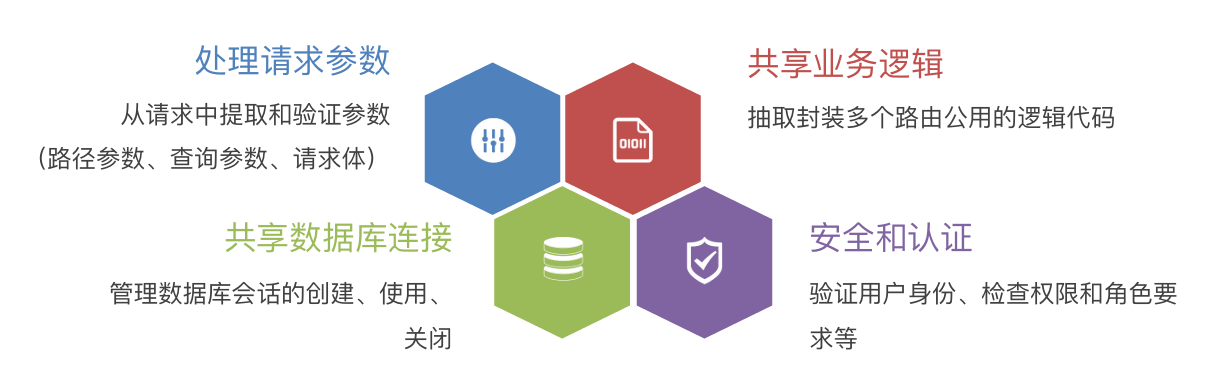
| 场景 | 说明 |
|---|---|
| 数据库连接 | 获取数据库会话 |
| 身份验证 | 验证用户身份 |
| 权限检查 | 检查用户权限 |
| 参数校验 | 统一的参数校验逻辑 |
| 日志记录 | 统一的日志处理 |
创建依赖注入步骤
-
创建依赖项:
async def common_parameters( skip: int = Query(0, ge=0), limit: int = Query(10, le=60) ): return { "skip": skip, "limit": limit } -
导入 Depends:
from fastapi import Depends -
声明依赖项:
@app.get("news/news_list'")
async def get_news_list(
    commons = Depends(common_parameters)
):
	return commons
例子:
from fastapi import FastAPI, Query, Depends  # 2. 导入 Depends

app = FastAPI()

# 分页参数逻辑共用: 新闻列表和用户列表
# 1. 依赖项
async def common_parameters(
    skip: int = Query(0, ge=0),
    limit: int = Query(10, le=60)
):
    return {"skip": skip, "limit": limit}

# 3. 声明依赖项 → 依赖注入
@app.get("/news/news_list")
async def get_news_list(commons=Depends(common_parameters)):
    return commons

@app.get("/user/user_list")
async def get_user_list(commons=Depends(common_parameters)):
    return commons
3、ORM(对象关系映射)
ORM(Object-RelationalMapping,对象关系映射)是一种编程技术,用于在面向对象编程语言和关系型数据库之间建立映射。它允许开发者通过操作对象的方式与数据库进行交互,而无需直接编写复杂的SQL语句
(1)ORM 优势
- 减少重复的 SQL 代码
- 代码更简洁易读
- 自动处理数据库连接和事务
- 自动防止 SQL 注入攻击
(2)常见的 ORM 框架
| 排名 | 框架 | 特点 | 适应场景 |
|---|---|---|---|
| 1 | SQLAlchemy ORM | 功能最强、最灵活、企业级 | 各类 API、微服务、数据应用 |
| 2 | Django ORM | 封装好、上手快 | Django 项目、管理后台 |
| 3 | Tortoise ORM | 全异步 | 异步 Web 服务、高并发 API |
(3)ORM 使用流程(以 SQLAlchemy 为例)
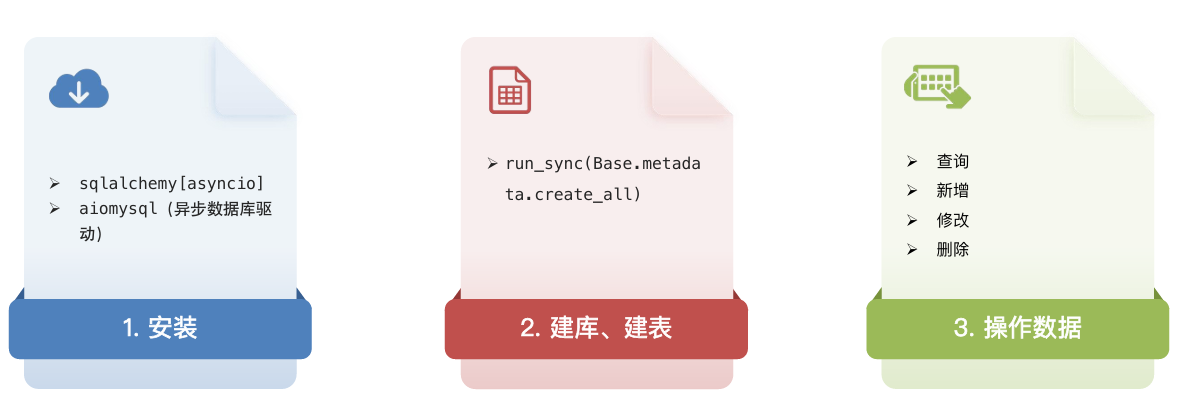
1. 安装依赖 → 2. 创建数据库引擎 → 3. 定义模型类 → 4. 启动应用时创建表 → 5. CRUD 操作安装依赖
pip install sqlalchemy
pip install aiomysql         # 如果使用 MySQL
pip install psycopg2-binary  # 如果使用 PostgreSQL
创建数据库引擎
使用 create_async_engine 创建异步引擎
# 1. 创建异步引擎

from sqlalchemy.ext.asyncio import create_async_engine

ASYNC_DATABASE_URL = "mysql+aiomysql://root:123456@localhost:3306/fastapi_test?charset=utf8"
# 123456: 密码
# fastapi_test: 数据库名

# 创建异步引擎
async_engine = create_async_engine(
    ASYNC_DATABASE_URL,
    echo=True,             # 输出 SQL 日志
    pool_size=10,          # 设置连接池中保持的持久连接数
    max_overflow=20        # 设置连接池允许创建的额外连接数,即最大连接数为 10 + 20 = 30
)
定义模型类
- 基类,继承
DeclarativeBase(包含通用属性和字段的映射) - 定义数据库表对应的模型类
# 2. 定义模型类: 基类 + 表对应的模型类
# 基类:创建时间、更新时间;
# 书籍表:id、书名、作者、价格、出版社

from sqlalchemy import DateTime, func, String, Float
from sqlalchemy.orm import DeclarativeBase, Mapped, mapped_column

class Base(DeclarativeBase):
    create_time: Mapped[datetime] = mapped_column(DateTime, insert_default=func.now(), default=func.now, comment="创建时间")
    update_time: Mapped[datetime] = mapped_column(DateTime, insert_default=func.now(), default=func.now, onupdate=func.now(), comment="修改时间")

class Book(Base):
    __tablename__ = "book"

    id: Mapped[int] = mapped_column(primary_key=True, comment="书籍id")
    bookname: Mapped[str] = mapped_column(String(255), comment="书名")
    author: Mapped[str] = mapped_column(String(255), comment="作者")
    price: Mapped[float] = mapped_column(Float, comment="价格")
    publisher: Mapped[str] = mapped_column(String(255), comment="出版社")
创建数据库表
- 从连接池获取异步连接,开启事务,执行 ORM 操作
- FastAPI 应用启动时,创建数据库表
# 3. 建表:定义函数建表 → FastAPI 启动的时候调用建表的函数

async def create_tables():
    # 获取异步引擎,创建事务 - 建表
    async with async_engine.begin() as conn:
        await conn.run_sync(Base.metadata.create_all)  # Base 模型类的元数据创建

# 启动 fastAPI 时建表
@app.on_event("startup")
async def startup_event():
    await create_tables()
在路由中使用 ORM
核心:创建依赖项,使用 Depends 注入到处理函数
from fastapi import FastAPI, Depends
from sqlalchemy.orm import Session

# 创建异步会话工
AsyncSessionLocal = async_sessionmaker(
    bind=async_engine,         # 绑定数据库引擎
    class_=AsyncSession,       # 指定会话类
    expire_on_commit=False     # 提交后会话不过期,不会重新查询数据库
)

# 依赖项,用于获取数据库会话
async def get_database():
    async with AsyncSessionLocal() as session:
        try:
            yield session             # 返回数据库会话给路由处理函数
            await session.commit()    # 无异常,提交事务
        except Exception:
            await session.rollback()  # 有异常,回滚
            raise
        finally:
            await session.close()     # 关闭会话

# 注入到路由中
@app.get("/book/books")
async def get_book_list(db: AsyncSession = Depends(get_database)):
    # 查询
    result = await db.execute(select(Book))
    book = result.scalars().all()
    return book
完整代码
from datetime import datetime
from fastapi import FastAPI, Depends
from sqlalchemy import DateTime, func, String, Float, select
from sqlalchemy.ext.asyncio import create_async_engine, async_sessionmaker, AsyncSession
from sqlalchemy.orm import DeclarativeBase, Mapped, mapped_column

app = FastAPI()

# 1. 创建异步引擎
ASYNC_DATABASE_URL = "mysql+aiomysql://root:123456@localhost:3306/FastAPI_first?charset=utf8"
async_engine = create_async_engine(
    ASYNC_DATABASE_URL,
    echo=True,         # 可选,输出 SQL 日志
    pool_size=10,      # 设置连接池活跃的连接数
    max_overflow=20    # 允许额外的连接数
)

# 2. 定义模型类: 基类 + 表对应的模型类
# 基类:创建时间、更新时间;书籍表:id、书名、作者、价格、出版社
class Base(DeclarativeBase):
    create_time: Mapped[datetime] = mapped_column(DateTime, insert_default=func.now(), default=func.now, comment="创建时间")
    update_time: Mapped[datetime] = mapped_column(DateTime, insert_default=func.now(), default=func.now, onupdate=func.now(), comment="修改时间")

class Book(Base):
    __tablename__ = "book"

    id: Mapped[int] = mapped_column(primary_key=True, comment="书籍id")
    bookname: Mapped[str] = mapped_column(String(255), comment="书名")
    author: Mapped[str] = mapped_column(String(255), comment="作者")
    price: Mapped[float] = mapped_column(Float, comment="价格")
    publisher: Mapped[str] = mapped_column(String(255), comment="出版社")

# 3. 建表:定义函数建表 → FastAPI 启动的时候调用建表的函数
async def create_tables():
    # 获取异步引擎,创建事务 - 建表
    async with async_engine.begin() as conn:
        await conn.run_sync(Base.metadata.create_all)  # Base 模型类的元数据创建

@app.on_event("startup")
async def startup_event():
    await create_tables()

@app.get("/")
async def root():
    return {"message": "Hello World"}

# 需求:查询功能的接口,查询图书 → 依赖注入:创建依赖项获取数据库会话 + Depends 注入路由处理函数
AsyncSessionLocal = async_sessionmaker(
    bind=async_engine,        # 绑定数据库引擎
    class_=AsyncSession,      # 指定会话类
    expire_on_commit=False    # 提交后会话不过期,不会重新查询数据库
)

# 依赖项
async def get_database():
    async with AsyncSessionLocal() as session:
        try:
            yield session             # 返回数据库会话给路由处理函数
            await session.commit()    # 提交事务
        except Exception:
            await session.rollback()  # 有异常,回滚
            raise
        finally:
            await session.close()     # 关闭会话

@app.get("/book/books")
async def get_book_list(db: AsyncSession = Depends(get_database)):
    # 查询
    result = await db.execute(select(Book))
    book = result.scalars().all()
    return book
4、ORM 操作数据
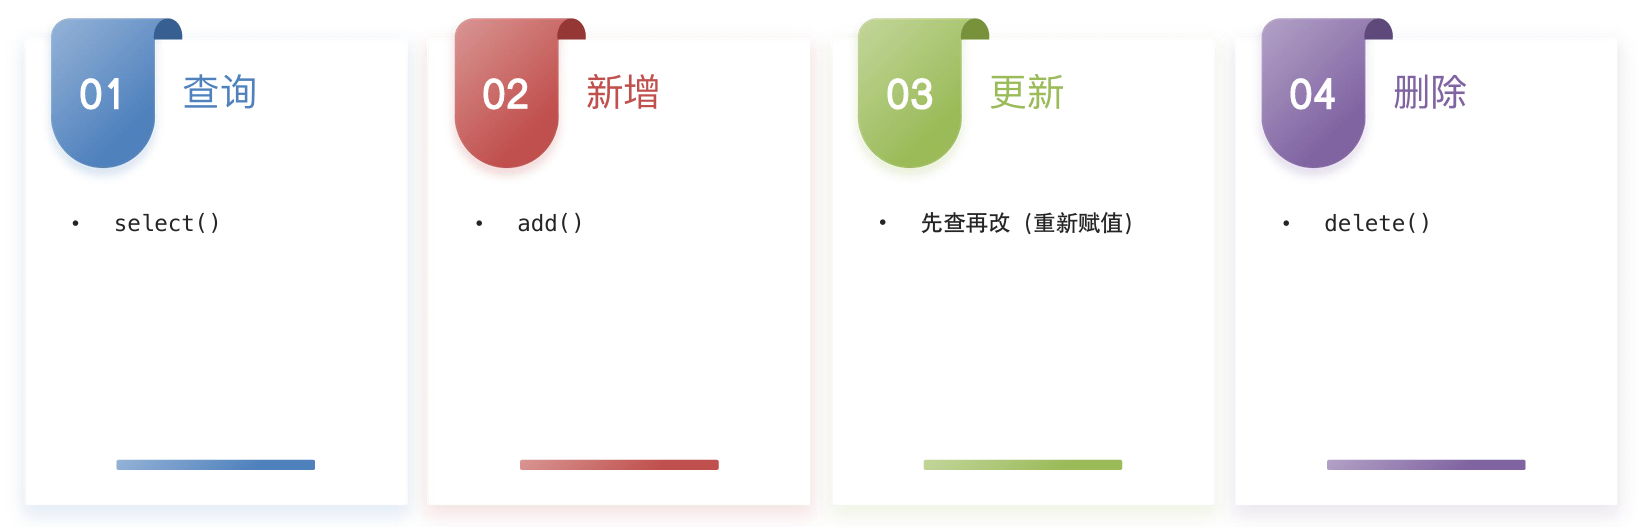
(1)ORM 查询操作
核心语句:await db.execute( select(模型类) ),返回一个 ORM 对象1) 基础查询
获取所有数据
scalars().all()
获取单条数据
scalars().first()get(模型类, 主键值)
例子:
@app.get("/book/books")
async def get_book_list(db: AsyncSession = Depends(get_database)):

    # 查询所有数据
    result = await db.execute(select(Book))
    book_all = result.scalars().all()

    # 查询第一条数据
    result = await db.execute(select(Book))
    book_first = result.scalars().first()

    # 根据主键查询数据
    book_by_id = await db.get(Book, 5)

    # 限制数量(只取前10条)
    result = await db.execute(select(Book).limit(10))
    book_limit = result.scalars().all()

    # 排序(升序),按id升序
    result = await db.execute(select(Book).order_by(Book.id))
    book_asc = result.scalars().all()

    # 降序
    result = await db.execute(select(Book).order_by(Book.id.desc()))
    book_desc = result.scalars().all()

    return {
        "all": book_all,
        "first": book_first,
        "by_id_5": book_by_id,
        "limit_10": book_limit,
        "asc": book_asc,
        "desc": book_desc
    }
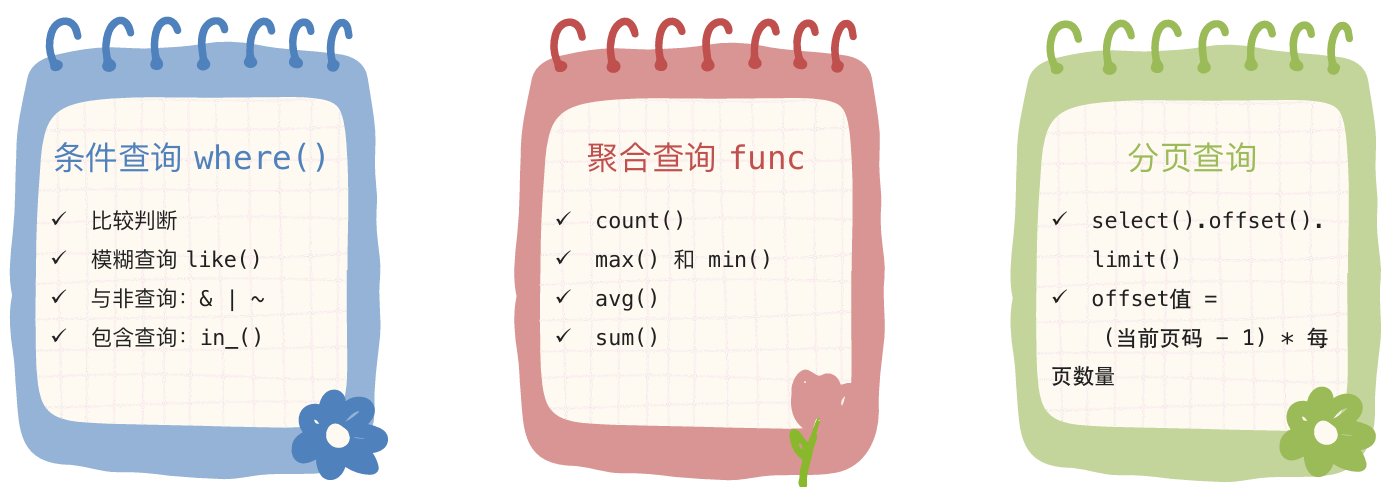
2) 条件查询
核心语法:select(Book).where(条件, 条件2, ...)条件:
- 比较判断:==; >; <; >=; <= 等
- 模糊查询:like()
- 与非查询:&; |; ~
- 包含查询:in_()
- 空值判断:is_(None)
/isnot(None)
from sqlalchemy import and_, or_, not_
from sqlalchemy import like, ilike

@app.get("/book/get_book/{book_id}")
async def get_book(book_id: int, db: AsyncSession = Depends(get_database)):

    # ==========比较判断:==; >; <; >=; <= 等==========
    # 等于
    result = await db.execute(select(Book).where(Book.id == book_id))
    book = result.scalar_one_or_none()

    # 不等于
    result = await db.execute(select(Book).where(Book.price != 0))
    books = result.scalars().all()

    # 大于、小于、大于等于、小于等于
    result = await db.execute(select(Book).where(Book.price >= 200))
    books = result.scalars().all()

    # ==========模糊查询:like() ==========
    # LIKE(区分大小写)
    result = await db.execute(select(Book).where(Book.author.like("曹_")))
    books = result.scalars().all()

    # ILIKE(不区分大小写)
	result = await db.execute(select(Book).where(Book.author.ilike("曹_")))
    books = result.scalars().all()

    # ==========与非查询:&; |; ~ ==========
    # 与或非
    result = await db.execute(select(Book).where((Book.author.like("曹%")) | (Book.price > 100)))
    books = result.scalars().all()

    # AND 条件
    # 写法一:多个 where 条件默认就是 AND
    result = await db.execute(
        select(Book).where(Book.price >= 100).where(Book.category == "小说")
    )
    books = result.scalars().all()
    # 写法二:用 and_() 显式连接
    result = await db.execute(
        select(Book).where(
            and_(Book.price >= 100, Book.category == "小说", Book.is_deleted == False)
        )
    )
    books = result.scalars().all()

    # OR 条件
    result = await db.execute(
        select(Book).where(
            or_(Book.price < 50, Book.category == "折扣书")
        )
    )
    books = result.scalars().all()

    # NOT 条件
    # 写法一:
    result = await db.execute(
        select(Book).where(not_(Book.is_deleted == True))
    )
    # 写法二:
    result = await db.execute(
        select(Book).where(Book.is_deleted == False)
    )
    # 写法三:
    result = await db.execute(
        select(Book).where(~Book.is_deleted)
    )
    books = result.scalars().all()

    # ==========包含查询:in_()==========
    # IN 查询
    result = await db.execute(select(Book).where(Book.id.in_([1, 3, 5, 7, 9])))
    books = result.scalars().all()

    # NOT IN 查询
    # 写法一:~Book.id.in_
    result = await db.execute(select(Book).where(~Book.id.in_([2, 4, 6, 8])))
    # 写法二:not_()
    result = await db.execute(select(Book).where(not_(Book.id.in_([2, 4, 6, 8]))))
    books = result.scalars().all()

    # ==========空值判断:is_(None)` / `isnot(None)==========
    # IS NULL
    result = await db.execute(select(Book).where(Book.description.is_(None)))
    books = result.scalars().all()

    # IS NOT NULL
    result = await db.execute(select(Book).where(Book.description.isnot(None)))
    books = result.scalars().all()

    return book
3) 聚合查询
聚合计算:func.方法(模型类.属性)- count:统计行数量
- avg:求平均值
- max:求最大值
- min:求最小值
- sum:求和
from sqlalchemy import func, select

@app.get("/book/count")
async def get_count(db: AsyncSession = Depends(get_database)):
    # 计数
    res_count = await db.execute(select(func.count(Book.id)))
    count = res_count.scalar()

    # 平均值
    res_avg = await db.execute(select(func.avg(Book.price)))
    avg_price = res_avg.scalar()

    # 最大值
    res_max = await db.execute(select(func.max(Book.price)))
    max_price = res_max.scalar()

    # 最小值
    res_min = await db.execute(select(func.min(Book.price)))
    min_price = res_min.scalar()

    # 和
    res_sum = await db.execute(select(func.sum(Book.price)))
    sum_price = res_sum.scalar()

    # GROUP BY(分组:按分类统计数量)
    res_group = await db.execute(
        select(Book.category, func.count(Book.id)).group_by(Book.category)
    )
    group_list = res_group.all()

    # HAVING(分组过滤:只返回图书数量大于2的分类)
    res_having = await db.execute(
        select(Book.category, func.count(Book.id))
        .group_by(Book.category)
        .having(func.count(Book.id) > 2)
    )
    having_list = res_having.all()

    return {
        "总数": count,
        "均价": avg_price,
        "最高价": max_price,
        "最低价": min_price,
        "价格总和": sum_price,
        "按分类分组统计": group_list,
        "分组后过滤(数量>2)": having_list
    }
补充:
func.count / func.avg / func.max / func.min / func.sum聚合函数,配合.scalar()获取单个数值- group_by:分组,select 里面非聚合字段必须放到 group_by
- having对分组后的结果做过滤(不能用 where,where 是分组前过滤)
- where:原始行过滤,不能使用聚合函数
- having:分组之后过滤,可以使用聚合函数
.all()用于 group_by,因为会返回多行多列(分类 + 数量),不能用 scalar ()
4) 分页查询
分页查询:select().offset().limit()- offset:跳过的记录数
- limit:返回的记录数
| 当前页码 | 每页数量(limit) | 跳过数量(offset) |
|---|---|---|
| 1 | 10 | 0 |
| 2 | 10 | 10 |
| 3 | 10 | 20 |
| 4 | 10 | 30 |
@app.get("/book/get_book_list")
async def get_book_list(
    page: int = 1,        # 页码
    page_size: int = 3,   # 每页数据
    db: AsyncSession = Depends(get_database)
):
    # 跳过数量 = (页码 - 1) * 每页数量
    offset_ = (page - 1) * page_size

    stmt = select(Book).offset(offset_).limit(page_size)
    result = await db.execute(stmt)
    books = result.scalars().all()

    return books
5) 总结
# 基本查询
db.query(Model).all()           # 获取所有
db.query(Model).first()         # 获取第一条
db.query(Model).get(id)         # 根据主键获取

# 条件过滤
db.query(Model).filter(Model.field == value).all()
db.query(Model).filter_by(field=value).all()  # 简化写法

# 排序
db.query(Model).order_by(Model.field).all()
db.query(Model).order_by(Model.field.desc()).all()

# 限制数量
db.query(Model).limit(10).all()

# 聚合
db.query(func.count(Model.id)).scalar()
db.query(func.sum(Model.field)).scalar()
(2)ORM 新增操作
核心步骤:定义 ORM 对象 → 添加对象到事务:add(对象) → commit 提交到数据库# 需求:用户输入图书信息(id、书名、作者、价格、出版社) → 新增
# 用户输入 → 参数 → 请求体
class BookBase(BaseModel):
id: int
bookname: str
author: str
price: float
publisher: str
@app.post("/book/add_book")
async def add_book(book: BookBase, db: AsyncSession = Depends(get_database)):
# ORM对象 → add → commit
book_obj = Book(**book.__dict__)
db.add(book_obj)
await db.commit()
return book(3)ORM 更新操作
核心步骤:查询 get → 属性重新赋值 → commit 提交到数据库# 需求:修改图书信息:先查再改
# 设计思路:路径参数书籍 id, 作用是查找;请求体参数, 作用是新数据(书名、作者、价格、出版社)
class BookUpdate(BaseModel):
bookname: str
author: str
price: float
publisher: str
@app.put("/book/update_book/{book_id}")
async def update_book(book_id: int, data: BookUpdate, db: AsyncSession = Depends(get_database)):
# 1. 查找图书
db_book = await db.get(Book, book_id)
# 如果未找到 抛出异常
if db_book is None:
raise HTTPException(
status_code=404,
detail="查无此书"
)
# 2. 找到了则修改:重新赋值
db_book.bookname = data.bookname
db_book.author = data.author
db_book.price = data.price
db_book.publisher = data.publisher
# 3. 提交到数据库
await db.commit()
return db_book(4)ORM 删除操作
核心步骤:查询 get → delete 删除 → commit 提交到数据库@app.delete("/book/delete_book/{book_id}")
async def delete_book(book_id: int, db: AsyncSession = Depends(get_database)):
# 先查再删 提交
db_book = await db.get(Book, book_id)
if db_book is None:
raise HTTPException(
status_code=404,
detail="查无此书"
)
await db.delete(db_book)
await db.commit()
return {"msg": "删除图书成功"}(5)ORM 使用注意事项
- 提交事务:增删改操作后必须调用
commit()提交事务 - 刷新对象:新增后使用
refresh()获取生成的 ID - 关闭会话:使用
finally确保会话被关闭 - 防止 SQL 注入:使用 ORM 参数化查询,避免字符串拼接
- 批量操作:大量数据使用
bulk_insert_mappings()或bulk_update_mappings()提高性能